
Code Video Model turns a scene brief into an editable Three.js program, renders that program as a proxy video, and uses MiniMax H3 to produce a detailed final clip. The important idea is executable previsualization: camera movement, object placement, and computed motion can be inspected before the video model adds appearance.
This guide follows the project site, official repository, and its inference entry point, reviewed October 14, 2026. It explains documented commands and implementation boundaries. We have not installed the environment, generated its examples, or verified its performance. H3Vid does not execute this repository's custom pipeline.
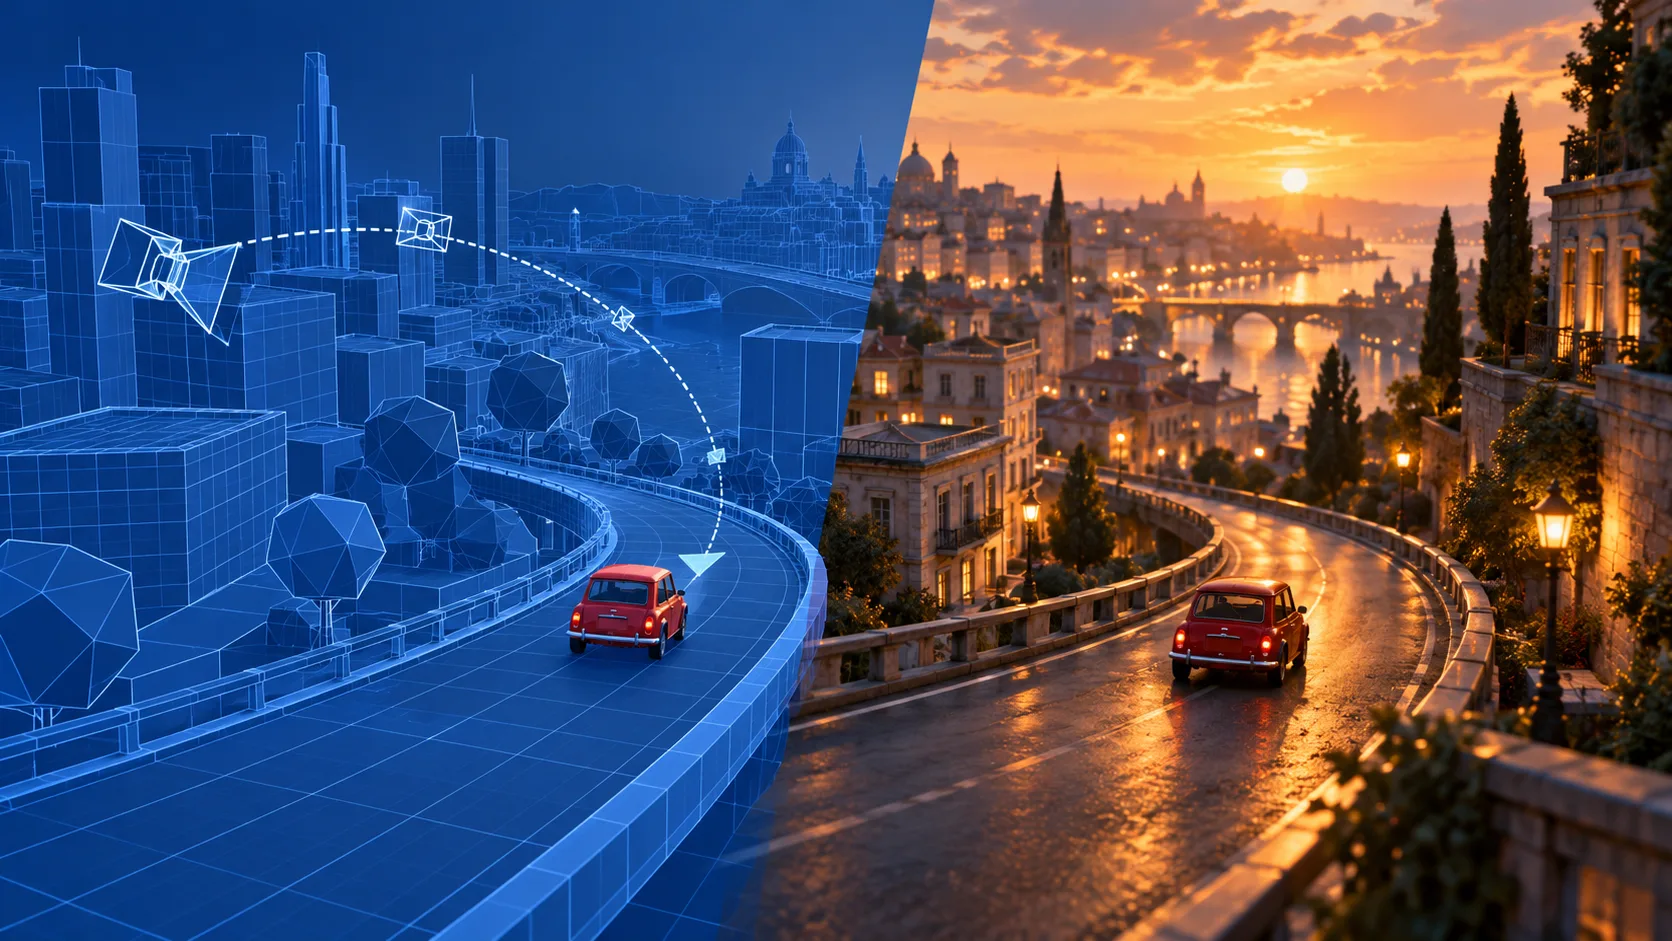
What code controls, and what H3 still generates
The program defines the scene and renders an inspectable motion reference. H3 then uses that proxy, a reference image, and text to synthesize the final appearance. Code controls the preview directly; it does not turn every pixel in the diffusion output into a deterministic render.
The project uses the proxy during early sampling steps to establish structure, then releases that conditioning so the final clip can avoid copying the proxy's flat look. This is a specific inference policy. Passing a rendered video to any generic reference-to-video endpoint does not prove the same schedule is being used.
The online H3 3D-to-Video workflow also accepts previsualization, but uses a separate H3 Max endpoint and product contract. That page answers the upload-and-generate intent. Code Video Model additionally answers how to generate editable scene code, review its geometry, and run the project's custom early-step conditioning locally.
Begin with a prepared example
The repository includes Sports Car, Tank Boarding, Loft Tour, and Robot Navigation examples. Each bundles a proxy video, reference image, and text prompt. Running a prepared set is a smaller first experiment than asking an agent to invent a scene, render it, create appearance references, and generate the final clip all at once.
The maintained environment specifies Ubuntu 22.04, a CUDA 12.6-compatible driver, Python 3.10, PyTorch 2.7.1, FFmpeg, and Chromium for rendering. Download the H3 reference-to-video checkpoint into the model directory described by the README. These are dependency requirements from the authors, not a hardware qualification performed by this site.
A documented inference request can look like:
python -m inference.generate_video \
  --code-video examples/sports_car/code_video.mp4 \
  --reference-image examples/sports_car/reference.png \
  --prompt-file examples/sports_car/prompt.txt \
  --model-root models/MiniMax-H3-ref2va \
  --text-device cuda:0 \
  --generation-device cuda:0 \
  --keep-steps 5 \
  --output outputs/sports-car-first-check.mp4
The explicit device flags are relevant: the reviewed entry point defaults text encoding to cuda:1 and generation to cuda:0. Pointing both to one GPU avoids assuming a second device exists, but does not establish that the complete model fits your card. Inspect memory requirements before running. The command refuses an existing output path, so use a fresh filename.
Build and inspect the proxy first
For a new scene, the Three.js stage uses a coding model to produce and refine a codebase. Its viewer exposes timeline playback, frame stepping, scene files, camera frustum, trajectory, and a world inspector. Use those tools to evaluate the motion before spending compute on H3.
For a moving car, verify that the road curve, steering direction, speed, and tracking camera agree. For a room tour, check that the camera does not cross walls or pass through furniture. A final generator cannot reliably fix an incorrect preview while also obeying it. Revise the code when the structural error originates in code.
Retain the program and rendered proxy together. An MP4 records the motion, while the program remains editable. Changing the scene code without rerendering its proxy creates a misleading workspace in which the files describe different shots.
Reference appearance needs alignment
The reference-generation stage offers strict alignment and a looser text-guided route. Strict alignment begins from the proxy's first frame and asks the image model to preserve composition and content while improving appearance. The looser route uses that frame as context but allows a text brief to change layout or viewpoint.
Choose deliberately. If the shot requires a car in a precise lane at a precise size, a heavily rearranged reference can conflict with the motion proxy. If appearance exploration is the goal, a looser reference may help, but inspect its spatial agreement before final video generation.
The documented reference stage creates a 1536×864 image. The reviewed video configuration uses 960×544, 124 frames, and 24 fps. Those are separate intermediate and final dimensions. Do not advertise the final clip as native 1536×864 because the appearance reference has that size.
Early-step guidance is not five-step generation
The reviewed configuration sets 20 total inference steps and five retained proxy-conditioning steps. --keep-steps 5 describes how long proxy guidance remains active; it does not reduce the complete denoising process to five steps. The CLI checks that this value lies between zero and the total step count.
For a useful comparison, retain all inputs and change only this guidance setting. Inspect structural obedience and whether the final style still resembles the low-detail preview. Such an evaluation can identify a tradeoff for your scene; it does not establish one universal best value.
Evaluation and practical limits
CodeVideoBench contains 22 cases across eight applications, with scene programs, proxies, references, prompts, and a viewer. The repository's evaluation script requests separate Structure, Style, and Quality judgments through an external model. Those scores are model-assisted evaluations, not human preference measurements or H3Vid tests.
Review structure directly as well: count objects, compare camera landmarks, inspect contact and collisions, and replay transitions. A scene can look attractive while violating its intended path. Keep the proxy visible beside the final clip so these differences remain inspectable.
The code repository uses Apache 2.0, while checkpoint and external-service conditions remain separate. The full workflow includes agent code generation, image generation, a custom H3 inference policy, and local rendering. Reproducing it online would require those stages and their artifacts, rather than relabeling the existing 3D generator. Start from the prepared example to identify which stage actually needs adaptation for your project.